Event Sourcing Explained: Patterns, Trade-offs, Use Cases
Event sourcing is an architectural pattern where every change to application state is recorded as an immutable, append-only domain event rather than overwriting a current-state row. The event log itself becomes the system's source of truth. It is particularly well-suited to billing systems, regulated workflows, and any domain where the full history of what happened matters as much as the current state.
What is event sourcing?
The event sourcing pattern stores every state change as an ordered, immutable domain event in an append-only log. Instead of overwriting a database row, the system writes a new event: PaymentReceived, SubscriptionCancelled, InvoiceIssued. Current state is derived by replaying those events from the beginning. The event log is the record of truth - no separate audit table required.
How event sourcing works: the mechanics
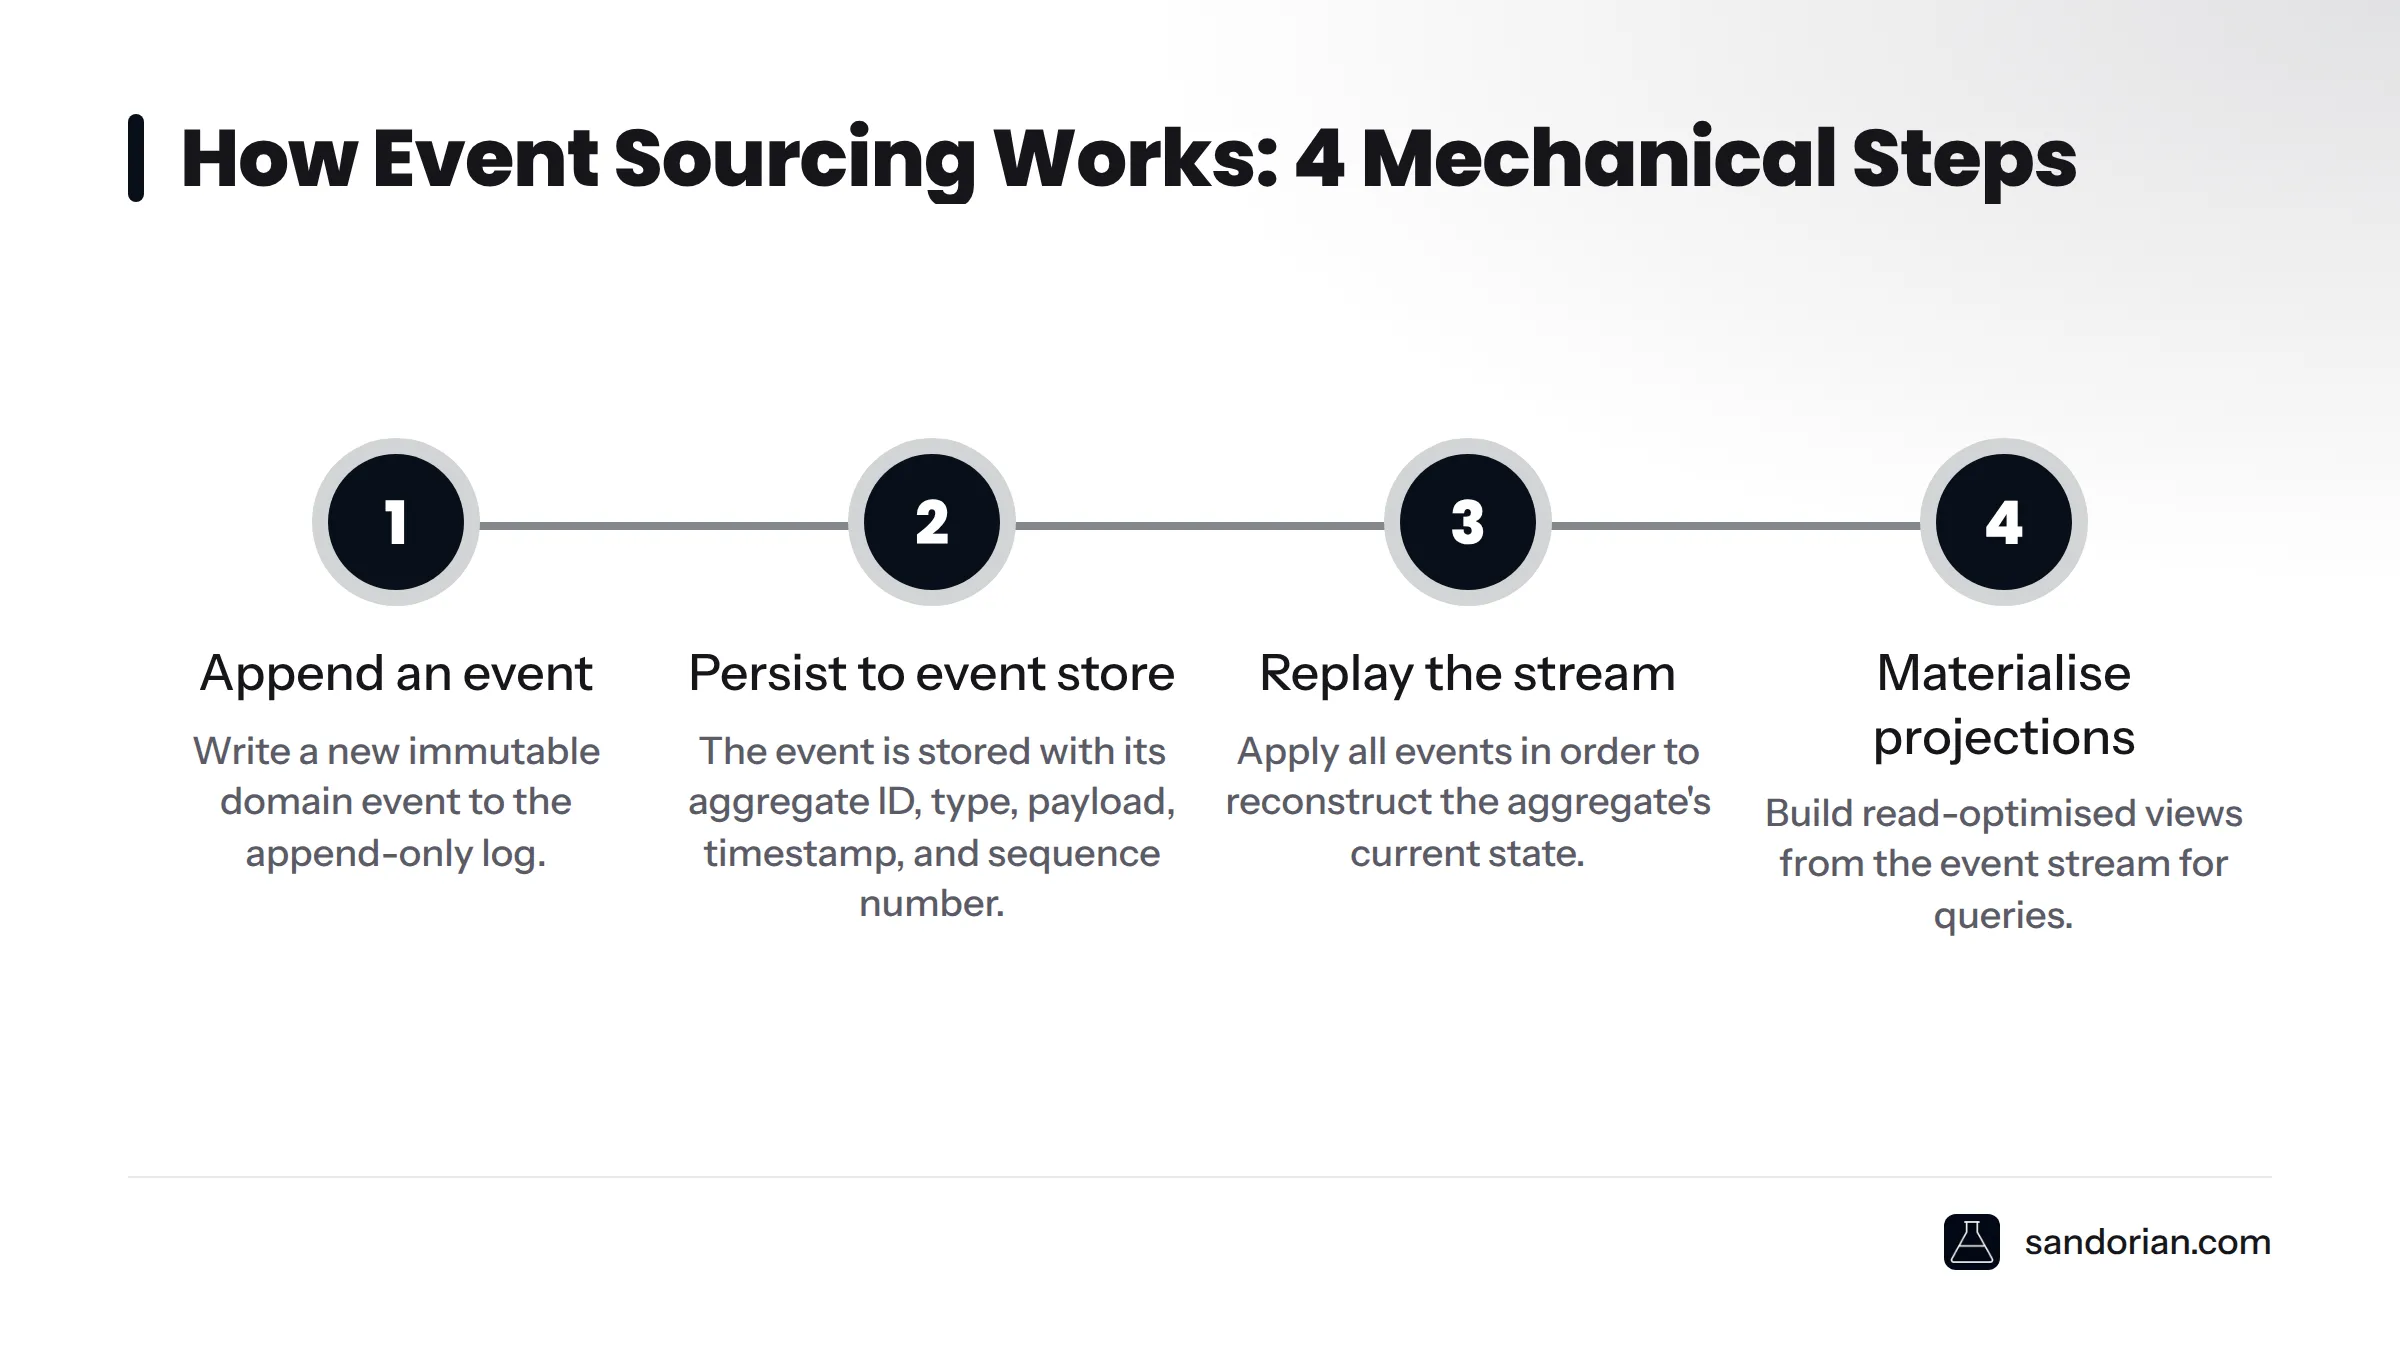
The pattern follows four mechanical steps that repeat continuously: append an event, persist it to the event store, replay the stream to reconstruct state, and materialise projections for queries.
The append-only event store
Events are written once and never updated or deleted. Each event carries a minimum set of fields:
- Aggregate ID - which entity (e.g., subscription
sub_00123) this event belongs to - Event type - a named business fact:
PaymentReceived,SubscriptionSuspended - Payload - the data relevant to that event (amount, currency, reason)
- Timestamp - when the event occurred
- Sequence number - the position of this event in the aggregate's stream
Purpose-built tools like EventStoreDB are designed around this model. PostgreSQL works too - an append-only table with a sequence column gets you 80% of the way there, which is often sufficient for teams starting out.
State reconstruction via event replay
To read the current state of a subscription, the system loads every event in that subscription's stream and applies them in order. Here is a concrete example:
SubscriptionCreated- plan: Pro, price: €49/monthPaymentReceived- amount: €49, period: October 2026PaymentFailed- reason: insufficient funds, date: November 1, 2026SubscriptionSuspended- triggered after failed payment
After replaying these four events, the aggregate's state is: suspended, last paid October, one failed payment attempt. No query against a mutable subscriptions table is needed.
Snapshots
Replaying four events is fast. Replaying 40,000 is not. Snapshots solve this: the system serialises the aggregate's state at a given sequence number and stores it alongside the event stream. The next replay starts from the snapshot and applies only the events that follow.
The trade-off is real. Snapshots add storage, schema management for the snapshot format, and invalidation logic. A snapshot strategy that performs well at 10,000 events can become a bottleneck at one million - snapshot cadence, storage format, and rebuild triggers all require deliberate design decisions, not afterthoughts.
Projections (read models)
A projection consumes the event stream and writes a queryable view optimised for a specific access pattern. A current_subscriptions read model might be a simple table with one row per subscription, updated each time a subscription event arrives. Projections are for reads; the event store is for writes.
The distinction between a snapshot and a projection in one sentence: a snapshot accelerates write-side replay for a single aggregate; a projection is a purpose-built read model built for query performance across many aggregates.
| Component | Role | Example |
|---|---|---|
| Event store | Persists the immutable event log | EventStoreDB, PostgreSQL append table |
| Domain event | A business fact, past tense, named | PaymentReceived, InvoiceIssued |
| Snapshot | Point-in-time aggregate state for fast replay | Serialised subscription state at event 500 |
| Projection | Queryable read model derived from events | current_subscriptions table |
| Aggregate | Consistency boundary that owns an event stream | One stream per subscription ID |
Core patterns in an event-sourced system
The domain event
A domain event is a business fact, not a technical signal. It is named in the past tense because it describes something that already happened: OrderPlaced, PaymentFailed, SubscriptionReinstated. This naming discipline matters. An event called UpdateSubscriptionStatus is an infrastructure signal masquerading as a domain concept. An event called SubscriptionSuspended is self-describing, auditable, and maps directly to a business rule. Martin Fowler popularised this distinction, and Greg Young's foundational work on event sourcing and CQRS built an entire architectural school around it.
The aggregate
The aggregate is the unit of consistency in domain-driven design. In an event-sourced system, each aggregate owns a stream of events. The aggregate enforces business rules before appending a new event. A subscription aggregate, for example, will refuse to append PaymentReceived if the subscription is already cancelled - the state derived from previous events tells it that rule would be violated. One stream per aggregate instance is the standard design: subscription-00123 contains every event that ever affected subscription 00123.
Idempotent event handling
Events can be delivered more than once - a retry mechanism, a network hiccup, or a failed acknowledgment can all cause duplicate delivery. Event handlers must be idempotent: processing the same event twice should produce the same result as processing it once. This is non-negotiable in billing, where a double-processed PaymentReceived event could credit an account twice. Our idempotent event handling guide covers the implementation patterns in depth.
CQRS alongside event sourcing
Event sourcing pairs naturally with CQRS because the separation is structural: the write model is the event store, the read model is the projection. The two are already distinct by design. CQRS is not required to practise event sourcing, but the two patterns reinforce each other cleanly. The CQRS sibling page covers the full pattern - this article stops at the seam.
Event sourcing ≠ event-driven architecture. Event sourcing is a persistence strategy: it defines how state is stored. Event-driven architecture is a communication strategy: it defines how services talk to each other. They are complementary, not alternatives. You can use event sourcing without EDA, EDA without event sourcing, or both together.
Benefits of event sourcing in billing and regulated workflows
This is where event sourcing earns its complexity cost. Generic systems get nice-to-haves; billing and regulated systems get structural requirements met.
Complete audit trail by default. Every state change is a named, timestamped, immutable fact. There is no separate audit log table to maintain, no trigger to forget to write, no UPDATE that silently erases history.
Time-travel queries. Replay a subscription's event stream up to any past timestamp and you have the exact state at that moment. "What was this subscription's status on the third of last month, before the failed payment?" is answered by replaying to that date - not by querying a history table that someone may or may not have built.
Zero silent data loss. Overwriting a database row destroys the previous value. In event sourcing, nothing is overwritten. Every intermediate state is recoverable.
Debugging via replay. Reproduce the exact sequence of events that led to a bug and apply them against a test environment. This is deterministic and precise in a way that log file analysis never is.
Natural fit for double-entry accounting logic. Financial transactions are already append-only by nature: you do not delete a ledger line, you write a correcting entry. Event sourcing maps to this model directly. Our double-entry ledger design page covers the ledger schema in full.
Regulatory environments. Many regulated industries require complete, tamper-evident change history as a structural property of the software. Event sourcing delivers this at the architecture level, not as a bolt-on. For a detailed treatment of audit trail design rules, see our designing audit trails guide. This article does not reproduce those rules - the sibling page owns that scope.
In billing systems we have built at Sandorian, event sourcing meant we could answer "what was this subscription's state on the 3rd of last month, before the failed payment, and why?" in seconds - without a separate audit log table.
Trade-offs and pitfalls Sandorian has encountered
Schema evolution is harder than it looks
Events are immutable. When an event schema changes - a field is renamed, a new required field is added, a type changes - every old event in the store must still be readable by the current codebase. The standard solution is upcasting: a transform function that converts old event payloads to the current schema on read. It works, but it accumulates. A system with three years of events and six rounds of schema changes carries six layers of upcasting logic that must all be maintained and tested. Teams consistently underestimate this cost until they try to rename a field in production for the first time.
Snapshot management adds operational overhead
Deciding when to snapshot (every N events? every N hours?), storing snapshots in a compatible format, and invalidating or rebuilding stale snapshots after a schema change all require disciplined engineering. The snapshot strategy that felt comfortable at 10,000 events per aggregate can buckle at one million when storage costs, rebuild times, and invalidation logic all scale together.
Read-side query complexity
Every query pattern needs an explicit projection. There is no ad-hoc SELECT * against the event log - running arbitrary queries against raw events is expensive and defeats the purpose of the read-side architecture. Teams coming from relational CRUD consistently underestimate how many projections they need to build and maintain for real product queries. This cost is front-loaded and permanent.
Eventual consistency is a business decision, not just a technical one
Projections can lag behind the write model by milliseconds to seconds under load. For many product contexts, this is fine. For others - a billing dashboard that must reflect a payment the customer just made - it creates UX or correctness issues. The business must accept this trade-off explicitly, not discover it after launch.
Steeper learning curve and team alignment
The mental model shift is real. Domain events, aggregates, projections, idempotent handlers - these require the whole team, not just the architects, to reason in a new way. A team that is not aligned on what a domain event is will produce infrastructure events dressed as domain events, and the entire value proposition of the pattern erodes.
Before adopting event sourcing, confirm your team can answer these five questions:
- Can you name ten domain events in your system right now, in past tense?
- Can you define the aggregate boundaries for your core entities?
- Does your business accept eventual consistency on reads?
- Do you have a plan for schema evolution over a two-year horizon?
- Do you have time to design explicit projections for every query your product needs?
When to use event sourcing - and when not to
Use it when:
- Your domain has a natural history: financial transactions, subscriptions, orders, lab sample tracking
- Auditability is a hard requirement - billing disputes, regulated industries, compliance-heavy workflows
- Time-travel queries or event replay for debugging are genuinely needed
- The "what happened" is as important to the business as "what is the current state"
- Your team has domain-driven design experience or is genuinely willing to invest in the learning curve
Do not use it when:
- Your domain is simple CRUD with no meaningful history - a CMS, a user settings page, a feature flag store
- Your team is small and deadline-constrained: the complexity cost is real and front-loaded
- Your read patterns are highly varied and ad-hoc - projections become a maintenance burden that grows with every new query pattern
- The business cannot tolerate any eventual consistency on reads
- You are retrofitting it onto a legacy system without a clear migration path
If you are unsure whether the pattern is warranted for your domain, our when event-driven architecture is overkill article covers the architectural signals that indicate simpler patterns will serve you better.
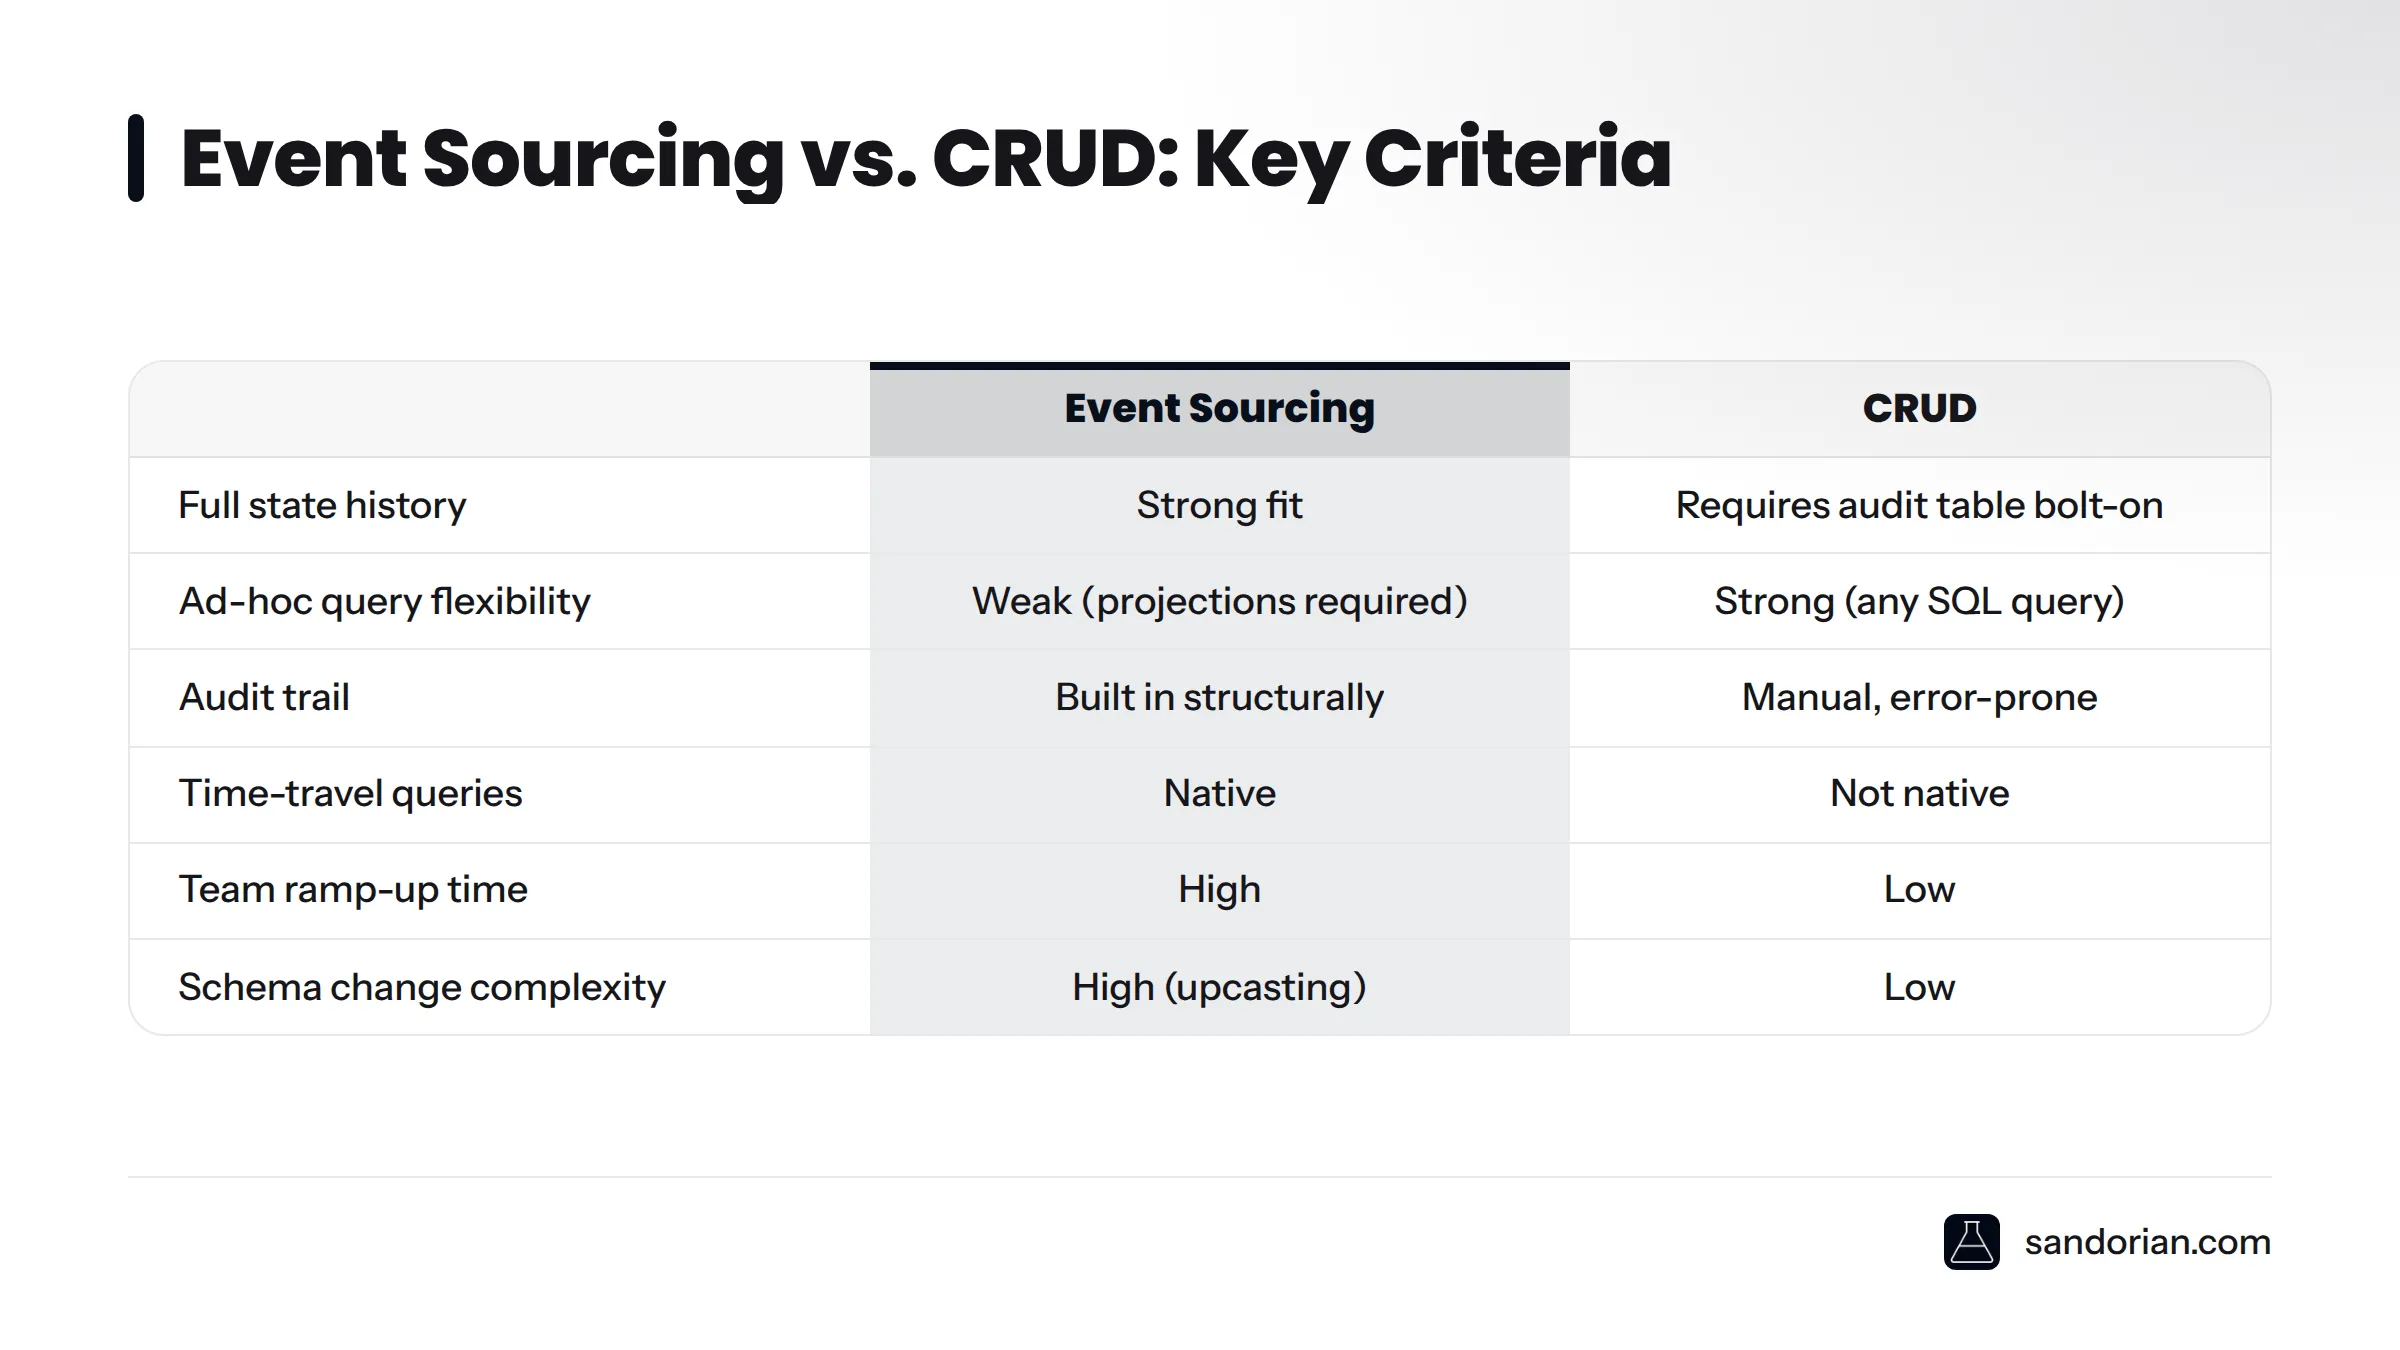
| Criterion | Event sourcing | CRUD |
|---|---|---|
| Full state history needed | Strong fit | Requires audit table bolt-on |
| Ad-hoc query flexibility | Weak (projections required) | Strong (any SQL query) |
| Audit trail | Built in structurally | Manual, error-prone |
| Time-travel queries | Native | Not native |
| Team ramp-up time | High | Low |
| Schema change complexity | High (upcasting) | Low |
| Simple CRUD domain | Overkill | Right tool |
| Billing / regulated domain | Right tool | Fragile at scale |
Event sourcing in practice: billing and regulated workflow examples
Subscription billing lifecycle
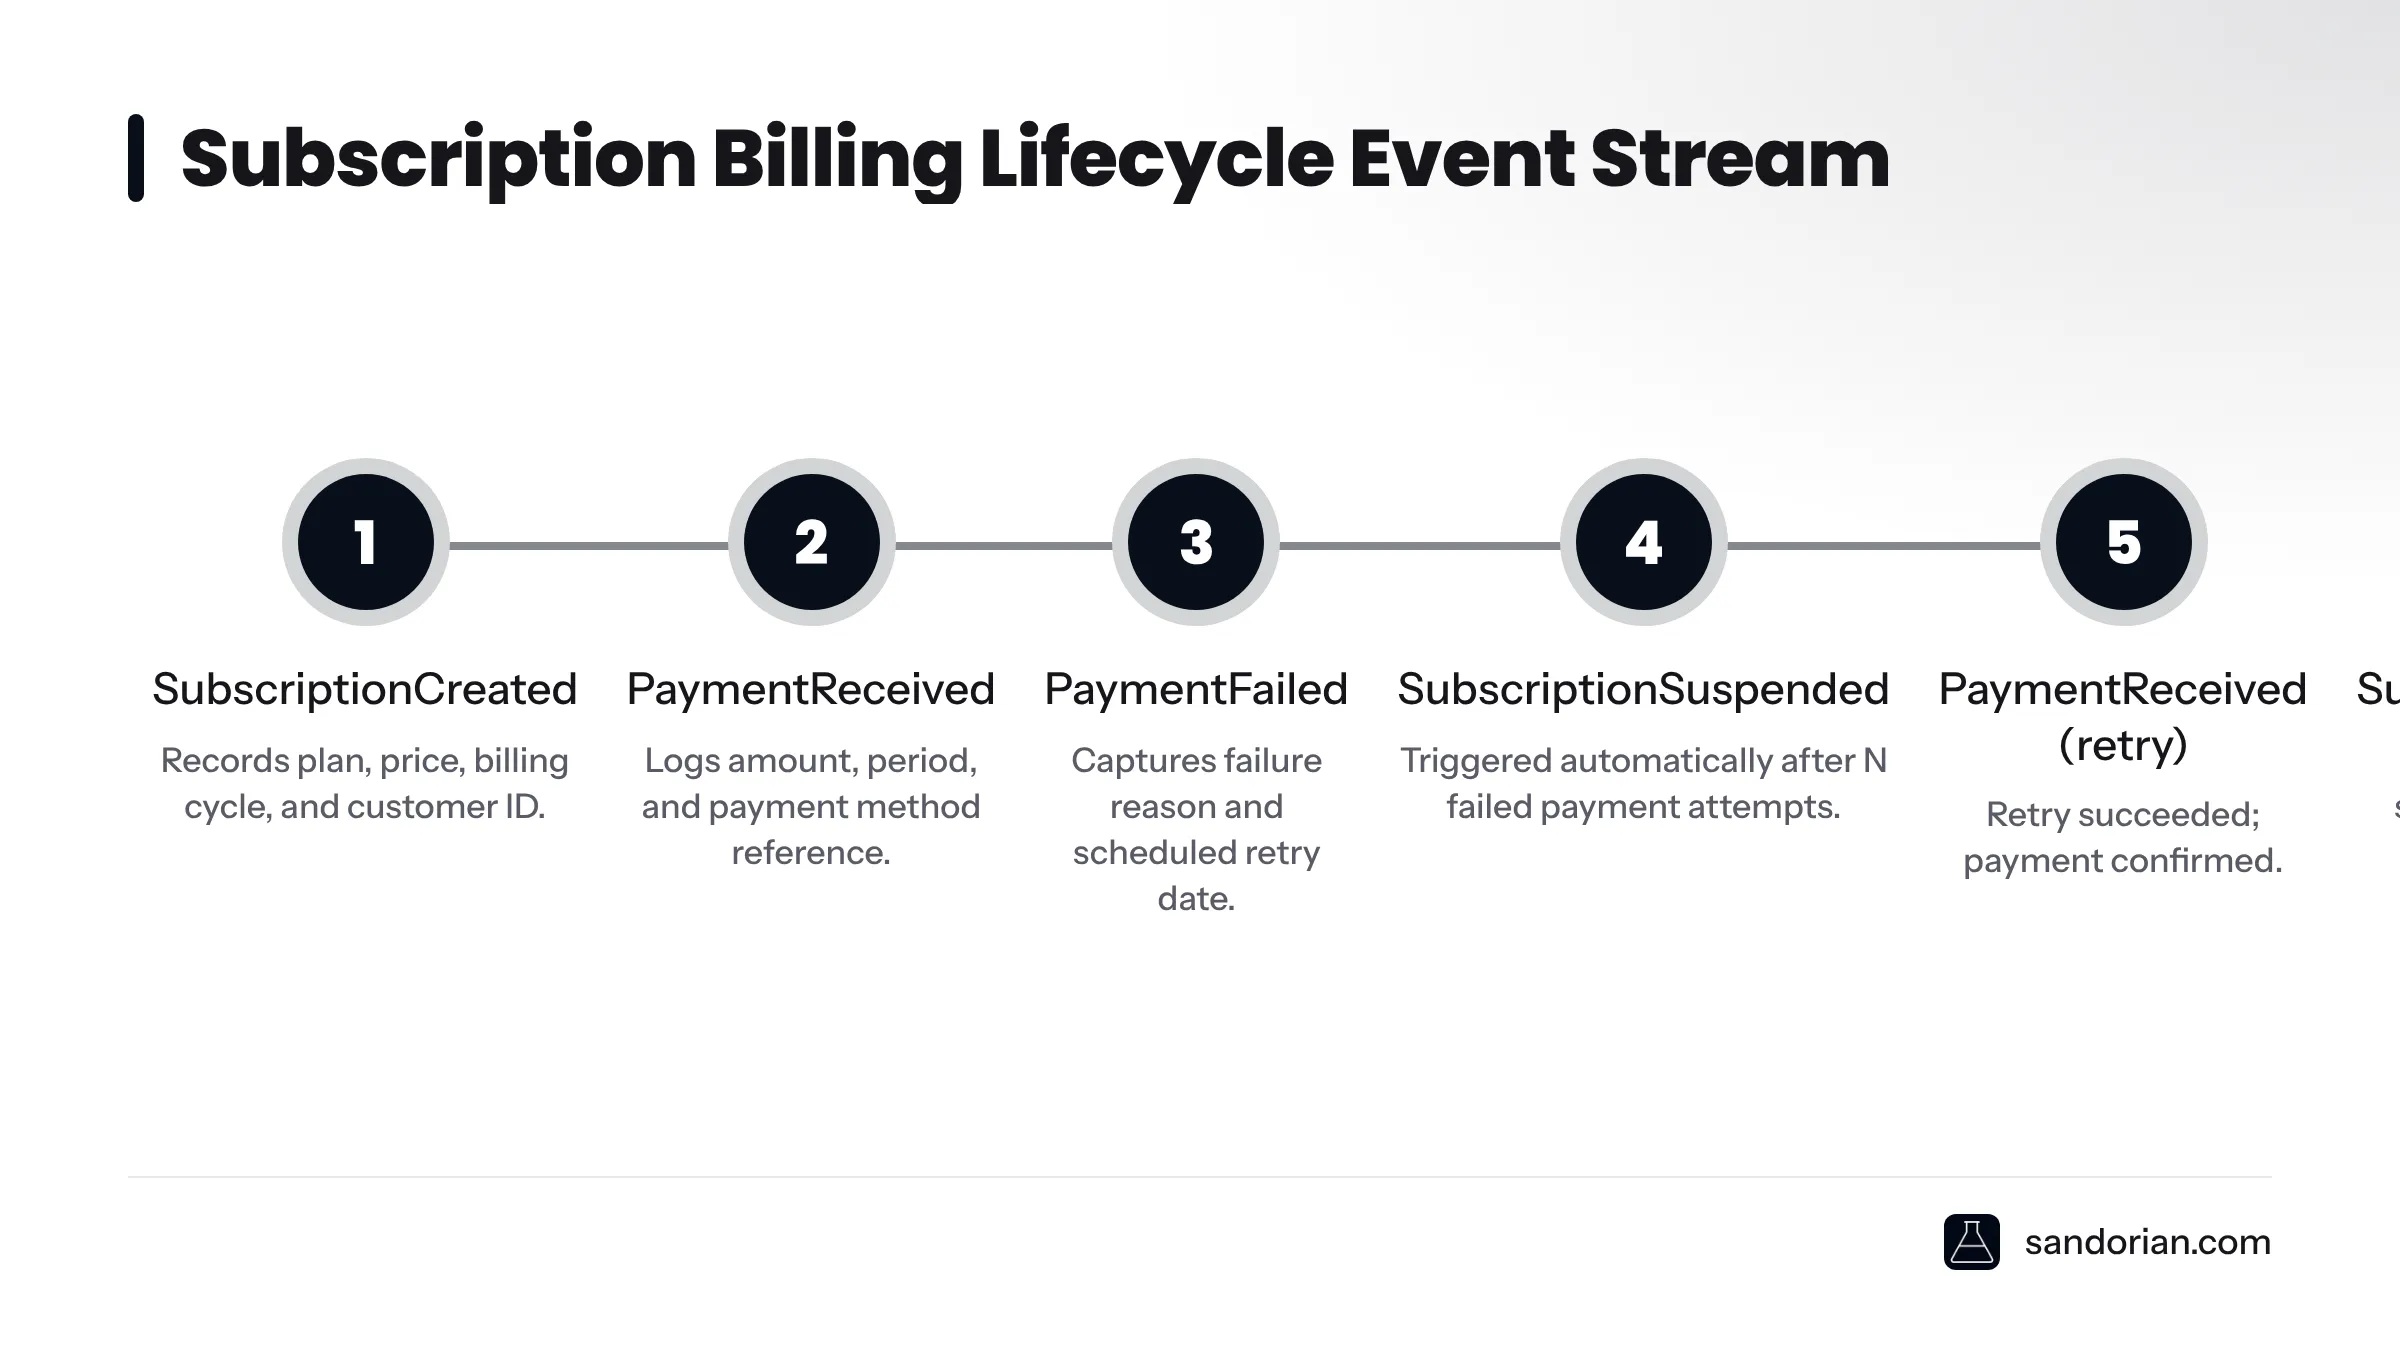
A subscription in an event-sourced billing system produces a stream like this:
SubscriptionCreated- plan, price, billing cycle, customer IDPaymentReceived- amount, period, payment method referencePaymentFailed- reason, retry scheduled dateSubscriptionSuspended- triggered automatically after N failed attemptsPaymentReceived- retry succeededSubscriptionReinstated- service restored
Replaying this stream at any point in time produces the exact subscription state at that moment. Billing period reconstruction, dispute resolution, and refund eligibility checks all follow from the stream - no reconstructed guess, no missing history. Our guide on subscription billing edge cases covers the scenarios where a mutable CRUD approach breaks under real billing complexity.
Invoice dispute resolution
When a customer disputes a charge, support teams in CRUD systems piece together the story from whatever audit columns the original developer thought to include. In an event-sourced system, the full event timeline is the answer. Every InvoiceIssued, PaymentAttempted, PaymentFailed, and CreditApplied event is there, in order, timestamped, immutable. Dispute resolution becomes a replay exercise, not a forensic reconstruction.
Regulated sample tracking
In regulated laboratory environments - where chain-of-custody for a physical sample must be documented at every stage - event sourcing provides the same structural guarantee it provides in billing. Each SampleReceived, SampleAssigned, AnalysisStarted, ResultRecorded, and CertificateIssued event forms an auditable chain. This is the same pattern we apply to lab workflow software at Sandorian; see our fintech software development practice page for the broader context of regulated-system builds.
In billing builds where payment reversals and refunds create complex state - a refund that partially reverses an invoice that itself corrected a previous invoice - event sourcing removed the need for compensating UPDATE logic entirely. The reversal events are facts in the stream. The state emerges from replay.
For a deeper treatment of how to take these patterns from design to a running system, our event sourcing implementation guide walks through the production steps in full.
Tooling options in 2026
You do not need a purpose-built database event sourcing tool to start. Here is where teams typically land:
- EventStoreDB - purpose-built, optimised for event streams, strong consistency guarantees, native projection support
- PostgreSQL with an append-only table - practical for most teams starting out; sequence column, JSONB payload, no deletes, no updates. Marten brings this pattern to .NET projects with a clean API
- Apache Kafka - high-throughput event log, often used as the event backbone in distributed systems; better suited to event streaming than to aggregate-level event sourcing
- Spatie Laravel Event Sourcing - the standard library for teams working in Laravel/PHP; wraps the pattern cleanly and integrates with Eloquent. Laravel and PHP teams can adopt event sourcing without leaving the framework
The right choice depends on team familiarity, expected event volume per aggregate, and whether you need cross-service event propagation or only single-service persistence.
Considering event sourcing for your billing or regulated system? Sandorian reviews architectures and helps teams avoid the pitfalls above - schema evolution strategy, snapshot design, projection planning, and the honest assessment of whether event sourcing fits your domain at all. Get in touch with Sandorian to start that conversation.
Frequently asked questions
What is the difference between event sourcing and event-driven architecture?
Event sourcing is a persistence strategy: it defines how a single service stores state - as an ordered log of immutable events rather than mutable rows. Event-driven architecture (EDA) is a communication strategy: it defines how services exchange information by publishing and consuming events over a message bus. The two are complementary. An event-sourced service can publish domain events to a bus for other services to consume, but event sourcing does not require EDA, and EDA does not require event sourcing.
Does event sourcing replace a traditional database?
Not exactly. An event-sourced system still uses a database - it uses it differently. The event store is a database (or a table in one) that only accepts appends. Projections are typically stored in a separate relational or document store optimised for reads. Think of it as two databases with different responsibilities: one for the truth of what happened, one for fast query access to current state.
What is an event store?
An event store is an append-only data store that persists domain events in the order they occurred. Each entry is immutable: no updates, no deletes. Events are grouped into streams, typically one stream per aggregate instance. Purpose-built options include EventStoreDB. A PostgreSQL table with a unique sequence column and a write policy enforcing no updates or deletes also qualifies.
What is the difference between a projection and a snapshot in event sourcing?
A snapshot is a write-side optimisation: it captures an aggregate's state at a given sequence number so that replay starts from there rather than from event zero. A projection is a read-side construct: it consumes the event stream and writes a queryable view - such as a current_subscriptions table - optimised for a specific query pattern. Snapshots speed up state reconstruction for individual aggregates; projections power the read layer of the system.
When is event sourcing a bad choice?
Event sourcing is the wrong choice when your domain is simple CRUD with no meaningful history - a CMS, a settings store, or any entity where the current value is all that matters. It is also a poor fit for small teams under deadline pressure, for systems with highly varied ad-hoc query needs (projections multiply quickly), and for products where the business cannot tolerate eventual consistency on read-side queries.
How does event sourcing help with audit trails?
Because every state change is recorded as a named, timestamped, immutable event, the audit trail is structural - it cannot be accidentally omitted. There is no separate audit table to maintain, no trigger to forget. Replay produces the exact sequence of facts that led to any current state. This is why event sourcing is a natural fit for regulated environments and billing disputes where tamper-evident history is required. For the design rules around audit trails, see our designing audit trails guide.
Can event sourcing be used with Laravel?
Yes. Spatie Laravel Event Sourcing is the primary library for Laravel/PHP teams. It handles aggregate roots, stored events, projectors, and reactors within the Laravel framework. Sandorian builds in PHP and Laravel and has used this approach in production billing systems. The pattern is framework-neutral at its core; Spatie's package removes most of the boilerplate.
Sources
- Event Sourcing - Martin Fowler, martinfowler.com
- EventStoreDB official documentation - eventstore.com
- Apache Kafka documentation - kafka.apache.org
- Marten - PostgreSQL-based document and event store for .NET, martendb.io
- Spatie Laravel Event Sourcing documentation - spatie.be
- Domain-driven design - Wikipedia
- Laravel Eloquent ORM documentation - laravel.com
Let's talk
We build the systems that power your business. Let us know how we can help.
Book a 30-min Call